Worth Reading: Ephemeral BGP Leaks
Doug Madory wrote an interesting article (published on APNIC blog) arguing that we shouldn’t worry about ephemeral BGP leaks that can be observed only during the BGP path hunting process that follows a route withdrawal.
I have to disagree with that. It’s never a good idea to ignore a dead canary in the coal mine.
While the ephemeral leaks do not impact the end result (after all, the route is gone), they are an important indicator of the lack of BGP route policy enforcement in the autonomous systems that propagate them. If an autonomous system is propagating a bogus route when no better routes are available, it’s equally likely to propagate a bogus route when an intruder manages to inject it.
D2DO303: Commiserating About AI with Ned and Kyler
Hosts Ned and Kyler compare notes on everything they’ve been doing with AI, including the successes they’ve enjoyed and headaches they’ve suffered building and implementing AI agents. They talk about how AI has sped up their workflows, how managing multiple AI agents is akin to raising toddlers, the necessity of using deterministic scripts for increased... Read more »The AI Agent Accountability Gap: Why Network Policies, API Gateways, And RBAC Are Not Enough
In The Five Pillars of AI Agent Accountability: A Diagnostic Framework for Engineering Leaders, we walked through each pillar of AI agent accountability (traceability, authorization provenance, identity and ownership, policy at scale, and human oversight) and argued that most enterprises today sit at Level 0 or Level 1 of the Accountability Maturity Model.
The most common reaction we get when we share that framework is some version of: “We’re already covered. We have network policies. We have an API gateway. We have RBAC.”
This article is for that reaction.
Enterprises aren’t starting from zero. Most have invested in security, networking, and identity infrastructure that works well for traditional workloads. The problem isn’t a lack of tools. It’s that existing tools were designed for model outputs, not autonomous actions; a world where services are deterministic, communication patterns are predictable, and humans make all the decisions.
Agentic AI breaks every one of those assumptions. Here’s where the most common approaches each leave a critical accountability gap.
Network policies: the wrong abstraction level
Kubernetes Network Policies are essential for securing any cluster. They restrict which pods can communicate with which other pods at the network level, and they should absolutely Continue reading
Iran’s Internet is partially restored, Cloudflare Radar data shows
On Tuesday, May 26, Iran’s vice president announced that Internet access had started to be restored in the country after being cut off almost three months ago, following the launch of U.S. and Israeli attacks on February 28.
Cloudflare Radar data confirms increased activity and indicates a partial restoration of the Internet in Iran. In this blog post, we’ll examine a range of data points that provide a lens into this prolonged shutdown – and the signs that Iran’s citizens are increasingly able to connect once again. As the situation continues to unfold, Radar will have the latest data on Iran’s connectivity.
Iranian citizens have experienced two national Internet shutdowns this year. The first began on January 8 around 16:30 UTC (20:00 local time), and we explored the impact seen over the first few days in a blog post. Traffic from Iran remained near zero until January 21, when a small amount of traffic returned, only to disappear a little over 24 hours later. A similar brief restoration also occurred on January 25, before traffic recovered more fully beginning on January 27.
In late February, as military strikes on Iran escalated, a second Continue reading
Chesterton’s Fence
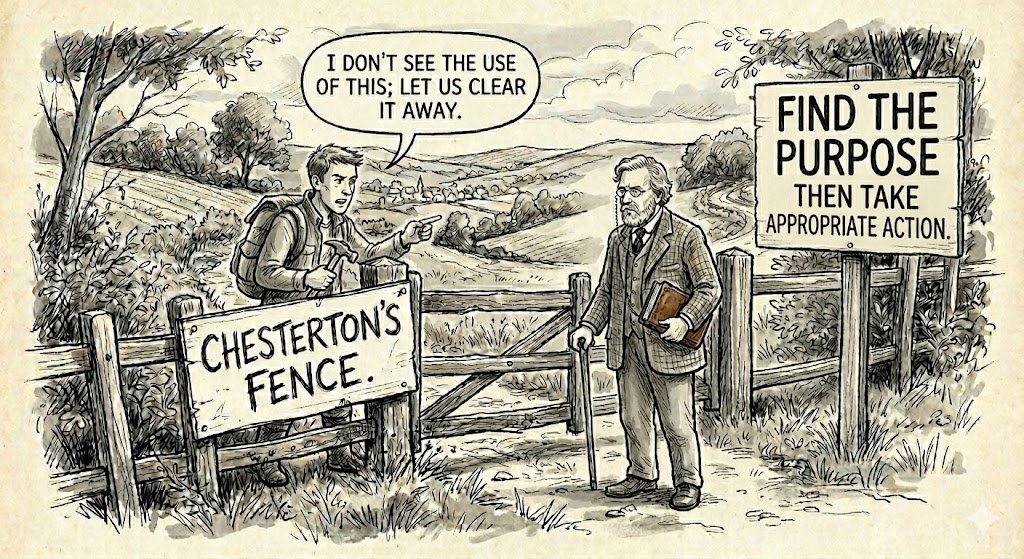
Imagine yourself walking down a country lane, lush green grass around you, no farm animals anywhere, when suddenly you see a fence right in the middle of the path. You think, now, that’s a bit silly, that fence is blocking the path, somebody should have this fence removed. And by thinking that you’d fall right into the predicament known as Chesterton’s Fence. That is, you see something that you instinctively feel does not belong and you want to remove it. And perhaps that is exactly what needs to be done, but not before you ask a very important question, “why”? Why is the fence here? What function does it serve? Who put it there? What were they trying to achieve?
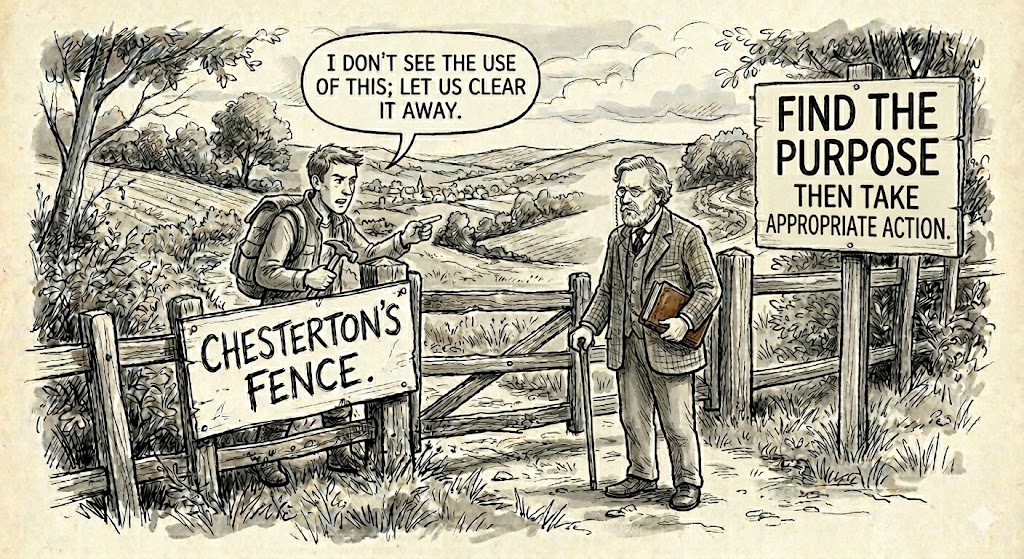
In any complex system, and most of the systems we work with these days are complex, problems often arise as a result of relationships and interactions between components. Our systems contain many components, some with special optimizations, some acting as local stabilizers, that might appear inefficient and unintuitive. Other components, or parts of the system seem to serve no apparent purpose at all.
Any given component is usually self-contained and can be understood, reasoned about, modified and improved by one Continue reading
SR Linux MPLS/VPN Configuration Notes
After fixing the SR Linux LDP configuration template, I decided to add MPLS/VPN to the netlab SR Linux MPLS features. After all, the one-page recipe seemed simple enough, more so as we already have tested VRF and EVPN templates.
Alas, nothing is as simple as it looks. There were two details that tripped me pretty badly.
DNS Centrality
As a collection of inter-twined markets, aspects of the Internet have been prone to excessive market distortions where one, or a small clique, of providers in market sector become completely dominant to the extent that there is no effective competition and no possibility of admitting additional market entrants. This form of market dominance is often termed "centrality". How centralised is the DNS?DNS Centrality
As a collection of inter-twined markets, aspects of the Internet have been prone to excessive market distortions where one, or a small clique, of providers in market sector become completely dominant to the extent that there is no effective competition and no possibility of admitting additional market entrants. This form of market dominance is often termed "centrality". How centralised is the DNS?The Case for VM and Container Consolidation in 2026
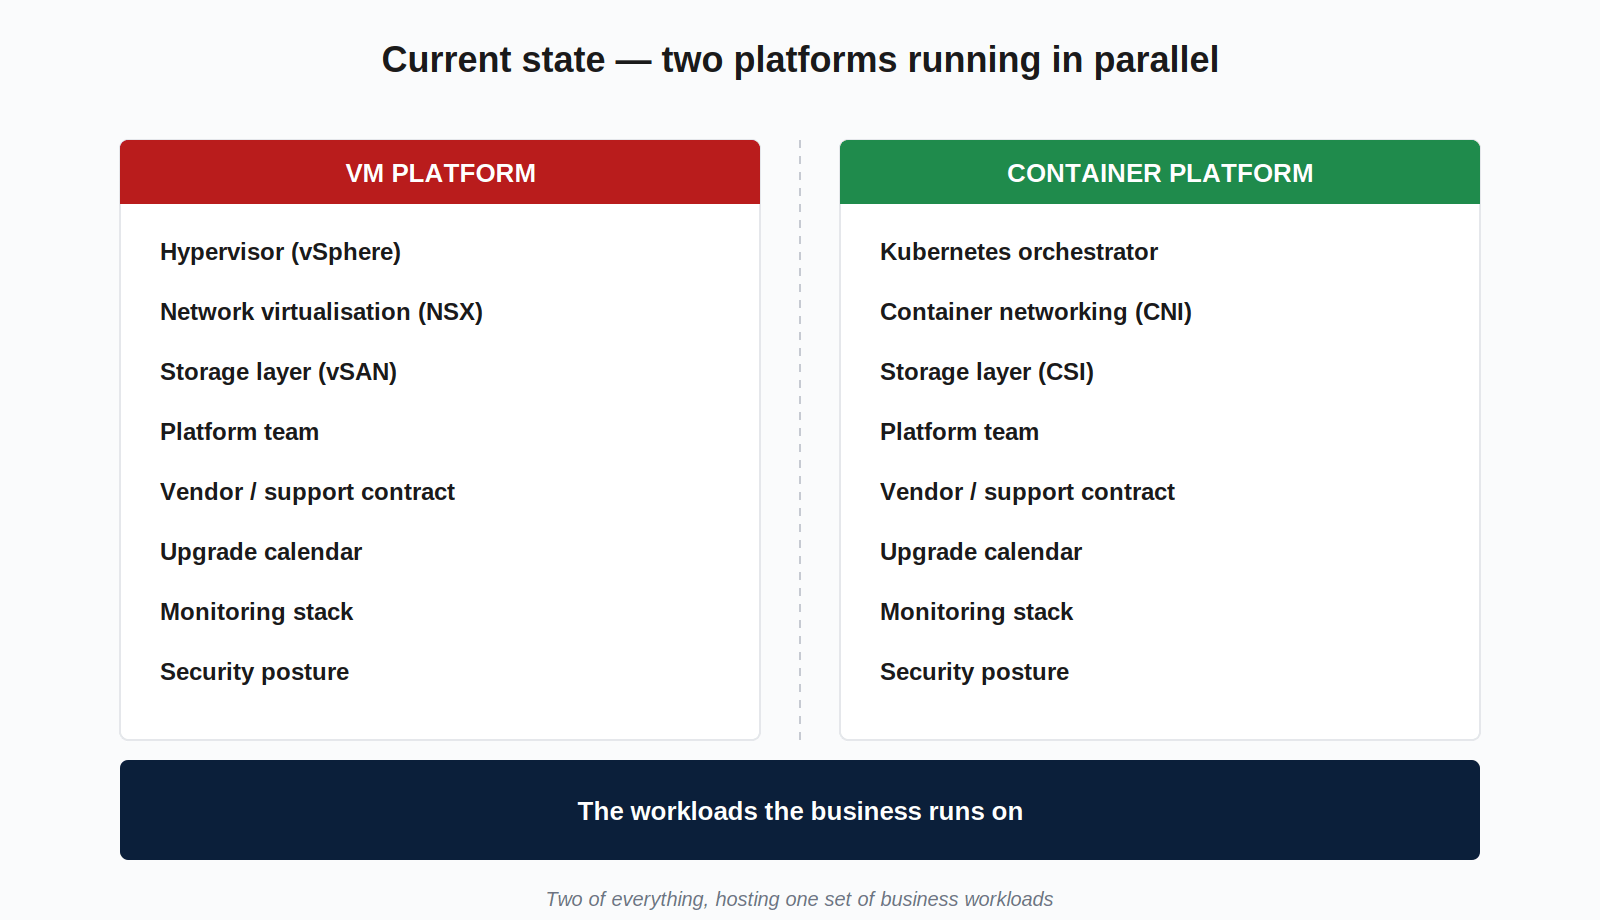
Two platforms, two teams, two procurement relationships, all doing one job. There’s a reason it ended up this way. There isn’t a reason it has to stay this way.
Ask anyone at a typical enterprise why the VM platform and the container platform are separate, and they’ll give you a sensible answer. The VM estate has been there for fifteen years. It runs the workloads the business depends on. Kubernetes got stood up later, when application teams started building microservices, and giving them their own environment made more sense than retrofitting one onto VMware. Two platforms, two teams, two roadmaps.
That’s how most enterprises got here.
The reasoning was sound at the time. The question is whether it still is.
This is the consolidation question most enterprises haven’t actually revisited, and it’s the one quietly absorbing more of your budget each year.
Why VM and container platforms ended up separate
If you operate both platforms, you know the shape of this already. There’s a VMware team: vSphere admins, network engineers who know NSX, storage specialists, plus a separate procurement relationship for the underlying virtualisation stack. Then there’s a Kubernetes team: platform Continue reading
PP111: New HPE Mist Features Validate NAC Changes, Enable Inline Microsegmentation (Sponsored)
HPE has announced new features in its Juniper Mist portfolio. On today’s sponsored Packet Protector, we dig into those features, including a dry run option that lets organizations test and refine Network Access Control (NAC) policies before pushing them out, a policy validation feature that can identify shadow NAC rules, and a microsegmentation capability aimed... Read more »HS133: Approaching Zero…Trust (Sponsored)
Most enterprises have some kind of zero trust strategy, but a lot of them could be better described as good intentions rather than active programs being implemented. Making good on a zero trust strategy and achieving an actual zero trust architecture requires tools that embody the core precept of zero trust thinking: deny access by... Read more »
HW080: WLAN Pros’ Wi-Fi Troubleshooting Course
The tool does not troubleshoot your network, you troubleshoot your network and the tool just shows you what’s there. If you don’t have a method, it doesn’t matter how many tools you have, you’ll just stare at more data. Today Keith is joined by Ferney Munoz to discuss a new course: the WLAN Pros Wi-Fi... Read more »NB576: IBM Gets Big Bucks to Build Quantum Chip Fab; AT&T Sues to Hang Up on Copper Phone Lines
Take a Network Break! We sound the alarm about a critical vulnerability in an on-prem Azure stack. On the news side, AI NetOps startup Selector adds public cloud observability to its portfolio, Versa Networks adds zero trust capabilities to its AI assistant, and IBM gets a billion-dollar investment to build a foundry to fabricate quantum... Read more »Worth Reading: Your Code Is Worthless
Did you manage not to stumble on a dramatic post explaining how someone generated 10,000 lines of code with AI while wasting time on your LinkedIn feed? Congratulations, you’re lucky.
However, as Nathaniel Fishel explained in his Your Code Is Worthless article, the “lines of code” is a useless vanity metric that sounds great in a LinkedIn self-promotion, but doesn’t matter when one has to maintain the product one has shipped to the customers. Add the natural laziness, and you have a perfect storm. As he wrote:
RustRadio UI improved
This is just a short followup to the last RustRadio post. If you came for more rants about C, you’ll be disappointed.
I’ve never been that interested in writing UI code, including HTML. You can see the “programmer art” in the screenshots linked from www.habets.pp.se.
And then the slightly different tech section, that doesn’t serve much of a purpose now that we have github.
I’ve not been happier with GTK, QT, and the others either.
But [RustRadio][rustradio] needs a UI.
I feel like the browser is the most stable and portable UI. So I’d already decided on that. So now I have to manually do a bunch of DOM manipulation, to create an interactive UI? Or worse, learn the React/Angular/Whatever flavor of the day, that will be obsolete by next afternoon? Gag me with a spoon.
LLM to the rescue
For now I’m just continuing to focus on the SDR and architectural parts of RustRadio, and I’m letting the LLM-written code do the HTML manipulation.
Yeah, it’s kinda vibe coding. But doesn’t use unsafe, and it demonstrably
outputs what I want. (I mean, sure it may require some follow-up prompts), so
who cares?
The Continue reading
Kubernetes Operational Maturity: Secure and Resilient Cluster Federation with Cluster Mesh
Practically no one runs a single Kubernetes cluster in production these days. Maybe that’s how it started but data sovereignty requirements, acquisitions, AI initiatives and the need for edge servers, among other considerations, have pulled most enterprises into multi-cluster territory whether they planned for it or not. Reaching Kubernetes operational maturity—the point at which a fleet of clusters operates as one secure, observable, policy-consistent system—depends entirely on how those clusters are connected. Operating in a multi-cluster environment has evolved into the unspoken standard, one requiring a careful re-evaluation of the network architectures used to link clusters together.
That re-evaluation rarely happens. Most enterprises connect their clusters with the same networking patterns they were using before Kubernetes existed: load balancers fronting internal services, DNS records published to external zones, and IP-based firewall rules. Those patterns were built for north-south traffic moving in and out of a traditional data center perimeter, not for east-west traffic moving between internal workloads.
Running east-west traffic on north-south plumbing
The conventional way to make services in one cluster reachable from another is to expose them externally with a load balancer in front, a DNS name registered in a public zone, a firewall rule allowing traffic in. Continue reading