Securing AI Agents Requires More Than a Gateway
Over the past year, I’ve spent a lot of time talking with engineering and platform teams about how they’re deploying AI agents. The conversations are changing. Six months ago, most were focused on getting agents into production. Now, increasingly, the question is how to secure them once they’re there.
It’s a familiar transition. We’ve seen it with containers, Kubernetes, microservices, and cloud infrastructure. New technology gets adopted, architectures evolve, and security has to catch up with how systems actually operate.
AI agents introduce some interesting challenges, though. Unlike traditional applications, agents make decisions about what to do next. They interact with models, invoke tools, communicate with other agents, access data, and execute code. A single user request can trigger a sequence of actions across multiple systems, sometimes with very little human involvement.
That changes the security problem.
An agent can be properly authenticated, operate within its assigned permissions, and still be led into doing something nobody intended.
It’s one of the reasons I believe securing agentic AI requires a defense-in-depth architecture, with controls operating at both the application and runtime layers.
The gateway is an important part of the architecture
AI gateways have become a natural place to introduce security Continue reading
Calico on Red Hat OpenShift 5: One Network and Security Model for Containers, VMs and AI
We’re pleased to announce that Calico is supported on Red Hat OpenShift 5, the latest version of the industry’s leading hybrid cloud application platform powered by Kubernetes. Tested and validated to run on Red Hat OpenShift 5, Calico delivers high-performance networking and zero-trust network policy for containers, virtual machines on Red Hat OpenShift Virtualization, and AI workloads, with one consistent policy model across the cluster.
Built on a long-standing collaboration
Calico has been a supported networking option for Red Hat OpenShift since OpenShift 4, and the Tigera Operator is listed in the Red Hat Ecosystem Catalog. Red Hat OpenShift customers can install Calico through the Tigera Operator on a new cluster, or move existing clusters from OVN-Kubernetes to Calico using Tigera’s documented migration path.
What Calico brings to Red Hat OpenShift 5
- High-performance networking, your choice of data plane. Calico runs on eBPF, iptables or nftables, so teams can match performance and operational needs cluster by cluster.
- Zero-trust network policy. Calico enforces Kubernetes NetworkPolicy and extends it with Calico’s own policy model, including cluster-wide rules, so default-deny and microsegmentation apply consistently.
- Policy you can test before you enforce it. Staged policies show the effect of a rule on live traffic Continue reading
Protect-RE Filter Generator Update – Mist, TACACS+, DHCP and Custom Rules
The Juniper Protect-RE Filter Generator on the Network Tools page picked up a round of additions. The trigger was simple: we compared it against the protect_re filter a Mist-managed EX4400 actually carries, and found a handful of things a real-world filter needs that the generator didn’t cover yet.
What’s new
- Mist-Managed Device. A Mist switch opens its connections outward, so the filter only has to accept the return traffic. Three optional terms cover it: outbound SSH (TCP source-port 2200), the Mist cloud over HTTPS (443), and NAC RadSec (2083). Each is TCP with
tcp-established, so a fresh inbound SYN doesn’t match. - TACACS+. Return traffic from your TACACS+ servers (TCP source-port 49,
tcp-established), with the server list pulled live fromsystem tacplus-serverusing the sameapply-pathtrick the BGP, NTP and RADIUS terms use. It’s TCP-only on purpose: TACACS+ doesn’t run over UDP, andtcp-establishedcan’t match UDP anyway, so a combined TCP/UDP term can only ever match TCP. - DHCP and DHCPv6. A client option for routers that get their management address by DHCP, and a server/relay option for routers that hand them out. The server/relay term is placed ahead of anti-spoof, because a client’s first packet comes from
Continue reading
Launching the Vite Ecosystem Fund
Cloudflare is distributing the first $301,300 of the Vite Ecosystem Fund to 44 projects and maintainers across the Vite ecosystem.
When VoidZero joined Cloudflare, we committed $1 million to strengthen the open source ecosystem around Vite. This round is just the start.
Sponsoring open source has always mattered, but now AI has made funding urgent.
AI is changing open source
AI has made open source more valuable while triggering more maintainer burnout. Previously, contributing to a project through either an issue or pull request meant you cared about it. In return, maintainers would review and provide feedback. AI changed the social contract of open source. Anyone can now create and submit AI-authored pull requests.
The most visible result is the influx of pull requests. As the number of PRs has gone up, the number of maintainers reviewing them has stayed constant. So each maintainer’s workload has grown.
During reviews, maintainers often find themselves speaking with an agent and not a person like they used to. If that’s the case, then why not cut out the middleman? Maintainers now have their own agents they can prompt to produce better results since they have more knowledge of the codebase.
AI has raised Continue reading
Worth Reading: BGP Multi-Homed with Two ISPs and Two Routers
I was reading the nice BGP Multi-Homed with Two ISPs and Two Routers scenario by Suresh Vinasiththamby - Packetswitch and thought wouldn’t it be nice if he were using netlab to build the lab, as that would give you the opportunity to build the same lab with zero hassle using non-Cisco devices. Guess what – Suresh already did just that. I was so glad to see someone using netlab in just the way I imagined it to be used.
Fakt: 65 % umgehen Zugriffsregeln, um arbeiten zu können
Lernen Sie, wie Sie Ihren gesamten Identitätsbereich schützen, ohne die tägliche Produktivität einzuschränken.The DO’s and Don’ts of Post-Quantum DNSSEC
There has been a lot of interest in recent months on the topic of post-Quantum cryptography (PQC) and DNSSEC. It appears likely that the day will come when our current suite of cryptographic algorithms could not resist efforts to break them using appropriately powerful quantum computers. Some folk say this day is decades away, while others are predicting we have just a small number of years. We have suitably strong quantum-resistant algorithms that we can use. The only problem is that these post-quantum digital signatures are up to 40 times as large as the signatures we use today. And this has some serious implications for the operation of DDNSSEC.AI Distributed Job Initialization
Job Orchestration and Resource Allocation
When a distributed training job
is launched, the cluster scheduler or orchestration layer (such as SLURM or
Kubernetes) allocates the required compute nodes and provides job-specific
information to the job launcher. This information includes the JobID, the
allocated nodes, and the resources assigned to the job.
The launcher provides the
configuration required by the Torchrun agents, such as the number of nodes, the
number of local workers, and the rendezvous configuration. Torchrun uses this
configuration and the rendezvous mechanism to establish the worker-group
membership and determine the distributed identities of the worker processes. These
include the global rank (RANK), local rank (LOCAL_RANK), total number of
workers (WORLD_SIZE), and number of local workers (LOCAL_WORLD_SIZE).
In a typical multi-node PyTorch
deployment, one Torchrun agent runs on each allocated node. The agent is a
host-side process responsible for launching and managing the local worker
group. It starts the configured number of worker processes, typically one per
GPU. Each worker is an independent operating-system process that executes the
training application and uses its assigned GPU for computation.
The Torchrun agent monitors the worker processes and manages their lifecycle, including restarting the worker group if a failure occurs and Continue reading
Going Further with Ansible and Juniper
This post is part of an ongoing series on Ansible, and you can find all the other posts in the series here.
In the previous part, we backed up the config of our Junos routers in two different ways. First, we used the junos_config module, which saved the config as set commands. Then, to get a copy in the curly bracket format, we ran show configuration with the junos_command module and saved the output to a file. In this section, I'll show you a more direct way to do it, using a module called juniper.device.config, which can retrieve the config and save it in whichever format we like.
Installing the Extra Packages
juniper.device.config is built on Juniper's PyEZ library, and it needs two extra Python packages, on top of the ones we installed in the previous part.
uv add junos-eznc jxmlease
- junos-eznc - Juniper's PyEZ library, which the module uses to connect to the router.
- jxmlease - Another library for working with XML, which PyEZ relies on.
The Playbook
The module doesn't create the directory for the backups, so let's create it first.
mkdir -p backups_native
Next, create a new playbook called backup_native.yml.
Continue readingGetting Started with Ansible and Juniper Junos
This post is part of an ongoing series on Ansible, and you can find all the other posts in the series here.
So far in this Ansible series, we've worked with Cisco and Arista devices. In this part, we're adding a third vendor, Juniper. We'll build a small lab with two Juniper routers, and use Ansible to configure their interfaces, IP addresses, and OSPF from scratch.
Juniper works quite differently from Cisco and Arista in a few areas, and that's really what this part is about. Instead of connecting over SSH and sending CLI commands, Ansible talks to Juniper devices using NETCONF. Every change goes into a candidate config and only takes effect once it's committed. And thanks to the way Junos compares configs, Ansible can show us exactly what it's going to change, in the same format as show | compare on the CLI.
This part is part of a series on Ansible for network engineers, so I won't go into every detail of things we've already covered, such as inventory, host_vars, loops, and check mode. If any of those are new to you, I recommend going through the earlier parts first. The OSPF example in this Continue reading
Revitalisasi Pasar Tradisional Lewat Sistem Digital Lokal
Pasar tradisional selama ini menjadi pusat ekonomi rakyat yang sulit tergantikan. Di sana, interaksi sosial, tawar-menawar, dan perputaran uang berlangsung setiap hari. Namun, di tengah perubahan pola belanja masyarakat, pasar tradisional menghadapi tantangan baru: persaingan dengan minimarket, marketplace daring, dan kebiasaan konsumen yang semakin mengutamakan kecepatan.
Untuk menjawab tantangan itu, banyak daerah mulai melirik revitalisasi pasar tradisional melalui sistem digital lokal. Tujuannya bukan mengubah pasar menjadi serba modern sampai kehilangan jati dirinya, melainkan membantu pedagang beradaptasi dengan kebiasaan belanja masa kini. Digitalisasi bisa menjadi jembatan antara tradisi dan kebutuhan zaman.
Mengapa Pasar Tradisional Perlu Beradaptasi?
Pasar tradisional punya kekuatan besar: kedekatan dengan warga, harga yang fleksibel, dan ragam produk segar. Tetapi, kekuatan itu tidak cukup jika fasilitas kurang nyaman, kebersihan kurang terjaga, atau layanan pembelian masih sangat bergantung pada cara lama. Konsumen masa kini ingin transaksi cepat, informasi harga yang jelas, dan kemudahan pembayaran.
Di banyak kota, pasar yang tidak beradaptasi mulai ditinggalkan pembeli muda. Mereka lebih memilih tempat yang rapi, punya akses digital, dan menyediakan pembayaran non-tunai. Jika tidak ada perubahan, pasar tradisional berisiko kalah bersaing meski sebenarnya memiliki potensi besar untuk tumbuh.
Revitalisasi digital hadir untuk menjawab masalah itu secara bertahap. Dengan pendekatan yang tepat, pasar bisa tetap Continue reading
Hedge 324: NOSTR
Social media services have largely become a marketplace designed to capture and hold your attention, rather than places where people share information and talk to one another. A large part of this is because they are hosted on large-scale platforms that must be paid for by large, centralized companies. NOSTR is taking a different direction, creating a protocol and system that can be hosted by anyone, anywhere, to build a social network. Wouter Constant joins Tom and Russ to explain what NOSTR is, and how it’s different.
You can learn more about NOSTR here.
download
The post-quantum future of web privacy
The highest priorities for the transition to post-quantum cryptography are the basic building blocks of authenticated key-agreement protocols such as TLS. Without these building blocks in place, secure communication on the Internet will not be possible once cryptographically relevant quantum computers come online. However, today we rely on quantum-vulnerable cryptography for much more than TLS.
Privacy Pass is a protocol used by site operators like Cloudflare to help protect applications from abuse. One way we do this is by rate limiting individual clients so that no one client consumes too many of the site's resources. Normally this involves some combination of friction or loss of privacy for users: CAPTCHAs or other challenges to moderate traffic, along with accounts and fingerprinting to identify traffic.Privacy Pass was designed to avoid this tradeoff between friction and privacy. The basic idea is that a client gets issued a number of tokens, which they can redeem in exchange for access to the site. Crucially, each token is unlinkable to the client it was issued to, ensuring the client can use the site as they always had without sacrificing privacy.
With 10 years of deployment experience under our belts — using Privacy Pass for applications Continue reading
Scriptable GeoDNS: leaving AWS for Bunny
To optimize the performance metrics of this blog, I relied on Amazon CloudFront to serve the assets,1 and Route 53 for the geo-aware DNS2 to direct readers to the closest host serving the content. But Route 53 is expensive: US$0.50 per zone per month, US$0.70 per million geolocation queries, and US$0.75 per healthcheck per month, plus US$1 per month for the KMS key needed to sign zones with DNSSEC. When I discovered that Bunny DNS is almost free for up to 500 domains and features scriptable answers, I made the jump! Plus, it's a European company based in Slovenia.
Bunny CDN
Bunny.net started as BunnyCDN in 2015. They added IPv6
support in 2017. Switching was uneventful. I don't bring a custom domain: I
serve the content from the b-cdn.net domain. As I depend on content
negotiation to serve AVIF and WebP images, I configure the CDN to cache
each image format separately.
I disable logging to avoid collecting personal information. While the bunny.net GDPR page promises they anonymize data, it is unclear what CloudFront keeps Continue reading
Meet NFA v26.04, featuring sharding & replication capability, host resource monitoring, and more
Noction Flow Analyzer v26.04 is now available, introducing ClickHouse sharding and replication, host resource monitoring, and application upgrades directly from the web interface. This release focuses on expanding database deployment options, simplifying system administration, and providing more control over traffic analysis and monitoring configurations.
Sharding and Replication
NFA v26.04 introduces support for sharding and replication, allowing flow and BGP data to be distributed across multiple database nodes rather than relying on a single database instance.
Sharding distributes data across multiple ClickHouse servers, providing a way to scale storage and query workloads as flow data volumes increase. Replication maintains copies of data across nodes, supporting database redundancy. Together, these capabilities provide additional deployment options for networks processing and retaining large volumes of flow data. For more details, check out our blog post or explore the documentation.
Host resource utilization monitoring
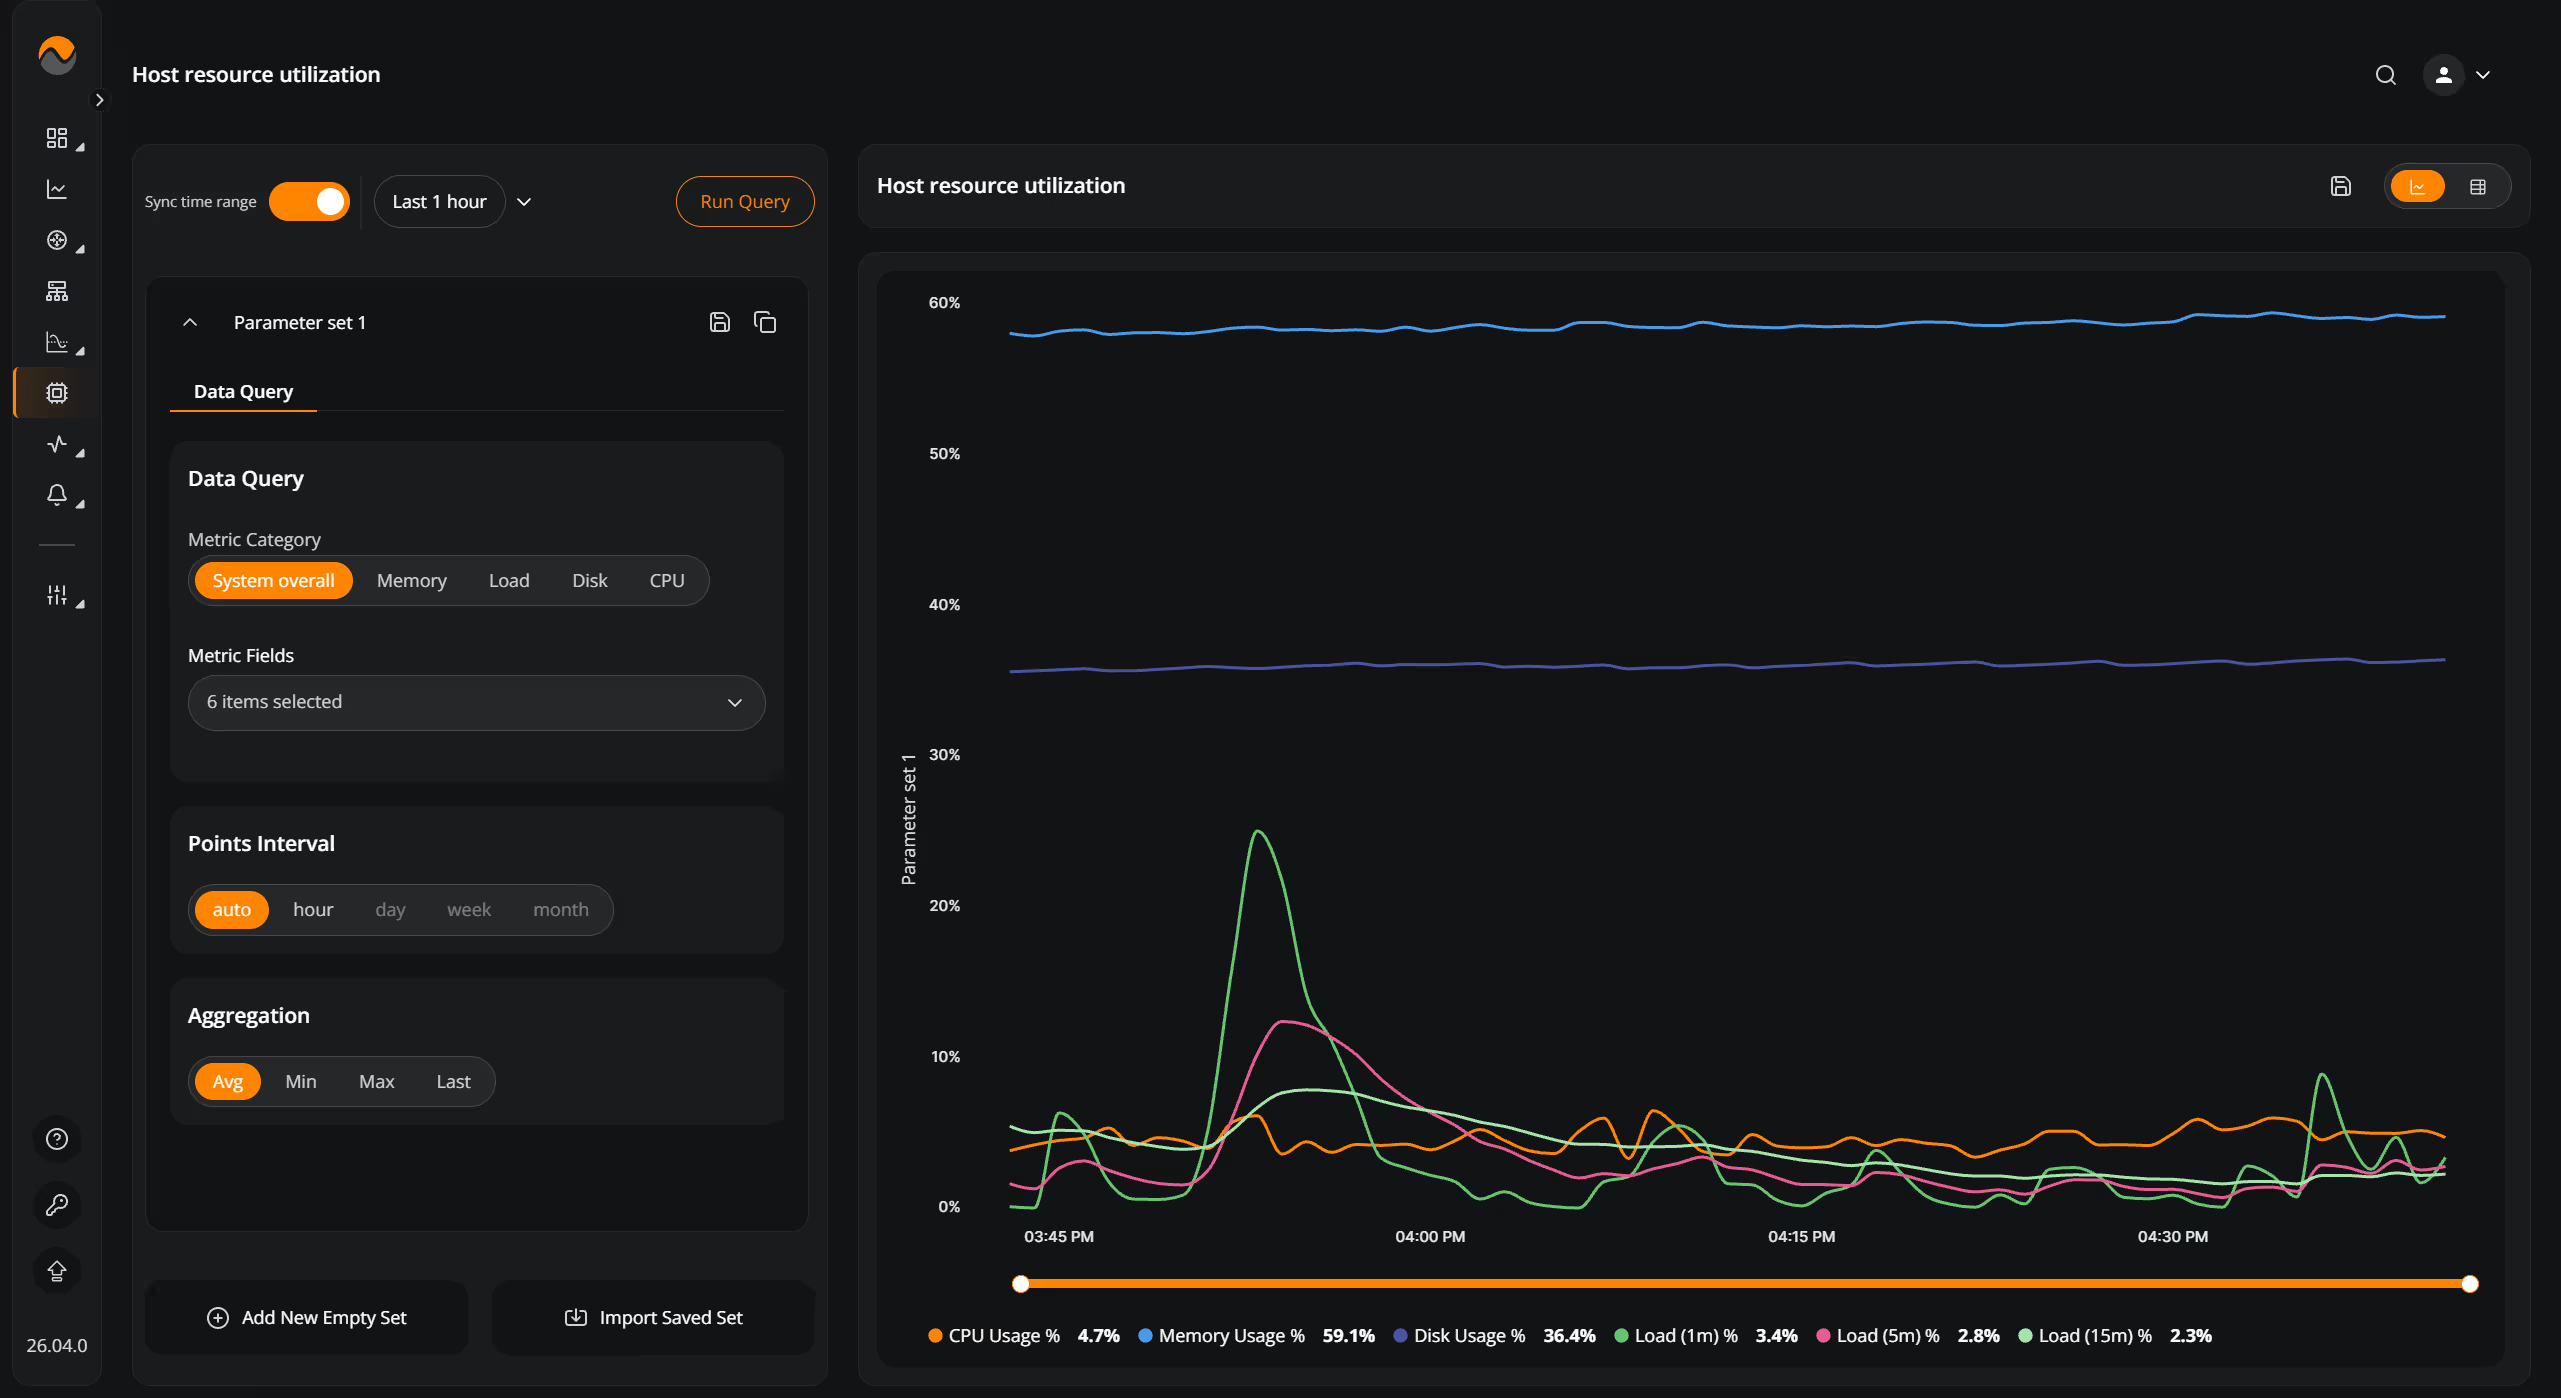
NFA now includes host resource utilization monitoring, providing visibility into the resource consumption of the server running the application. Administrators can monitor server resource usage alongside NFA operations, making it easier to identify resource constraints and assess infrastructure requirements. This provides additional context when investigating system performance or planning capacity for growing flow data volumes.
Application upgrades through the Continue reading
ClickHouse Sharding and Replication in NFA
Noction Flow Analyzer (NFA) uses ClickHouse to store and analyze traffic information collected from NetFlow, sFlow, IPFIX, J-Flow, and NetStream exporters. In a typical installation, the ClickHouse database runs on the same server as NFA. This arrangement keeps deployment and administration relatively simple, and it works well when the server has enough resources for incoming data, historical storage, and analytical queries.
Larger monitoring environments can have different requirements. A growing number of exporters, longer retention periods, or more demanding reports may put increasing pressure on the database server. Some operators also want a second copy of their stored traffic data so that an individual storage-node failure doesn’t leave the dataset inaccessible.
NFA’s sharding-enabled ClickHouse architecture addresses these requirements by supporting multiple database shards and replicas. The implementation retains a single-node default configuration. Additional ClickHouse servers can be introduced when storage capacity or redundancy becomes a concern, without requiring a complete NFA application installation on every database node. The architecture covers both flow data and BGP routing information. Each uses a sharding key based on its own record attributes, while the underlying distributed storage and replication mechanisms remain the same.
Starting with the existing NFA database structure
NFA uses MySQL for Continue reading