We’re open-sourcing our privacy proxy CLI

Debugging privacy-preserving protocols is hard. Oblivious HTTP has several different steps across four different parties, not to mention binary HTTP encoding and details spread across many draft RFCs. We've taken what we've learned operating protocols like Oblivious HTTP at the scale of millions of requests per second, and wrapped it up in a nice, clean CLI tool — that we are open-sourcing today.

We call it our privacy-client, or pvcli. We’re releasing it under the Apache-2.0 License, and it is open for contributions.

Here’s a single line of code that executes a full Oblivious HTTP request with a relay, gateway and origin. Don't worry if you don't know what that means, we'll cover it below.

We’ll explain why we built this tool, and show just how handy it can be.

Why privacy protocols can be hard to debug

Let’s take a closer look at our motivation for creating pvcli. Over time, the Privacy team’s product suite and customer base grew. We added products like Privacy Proxy and Privacy Gateway, which power Apple’s Private Relay, Microsoft’s Edge Secure Network VPN, Flo Health’s Anonymous Mode, and more. With it came an increasing amount of special customer requirements, Continue reading
Extending Automatic Anomaly Detection in Noction IRP v4.3.1: new reflection & amplification attack coverage

aad

Automatic Anomaly Detection in IRP

Noction IRP v4.3 added Automatic Anomaly Detection (AAD), a behavior-based traffic analysis engine built into the Intelligent Routing Platform. Instead of fixed thresholds, AAD watches traffic telemetry from NetFlow, sFlow, or mirrored traffic and builds its own baseline for what “normal” looks like on a given network. When traffic breaks from that baseline for a sustained stretch (a packet-rate spike, one protocol suddenly dominating, an inbound surge with nothing matching it outbound), AAD flags it and can trigger mitigation through IRP’s existing BGP controls: Remote Triggered Blackholing and BGP FlowSpec.

At launch, AAD already covered DNS and NTP amplification, UDP floods, TCP SYN/ACK floods, HTTP(S) floods, SSH floods, and ICMP/Smurf-style attacks.

Additional vectors covered

Reflection and amplification attacks stay popular because they’re cheap to run. An attacker spoofs a victim’s IP address, sends a small query to an open, publicly reachable service, and lets that service handle the work of sending back a much larger response. CISA’s advisory on UDP-based amplification attacks lists a long list of exploitable protocols beyond DNS and NTP, and vendor telemetry from Netscout and Akamai continues to show these vectors being abused, largely because so many misconfigured, internet-facing Continue reading

Migrate First, Modernize Later: A Leadership Guide to Converging VMs and Containers to Run AI Workloads

The Tipping Point

Every so often the ground under enterprise IT moves. It’s moving now. Across industries, organizations are consolidating fragmented infrastructure onto a single, self-hosted platform capable of running both containers and virtual machines side by side. The motivation is simple: simplify operations, lower cost and reallocate resources & budget to AI initiatives. Kubernetes is emerging as the primary platform for many of these workloads.

For most IT leaders, the compute and storage portions of a VM migration are manageable. Storage arrays and hypervisor CPU/memory allocation translate fairly directly to Kubernetes equivalents. Networking is where migration plans stall. A VM’s network identity — its IP, its VLAN membership, its firewall rules — is wired into surrounding infrastructure, monitoring, compliance controls, and business processes that nobody wants to touch during a migration window.

Teams accustomed to NSX for this work find that native Kubernetes networking wasn’t built with VM administrators in mind, and the functionality gap becomes the reason migration projects get bigger or are stalled. If the networking problem is solved — if a VM can move to Kubernetes and keep its IP, its policy, and its security posture intact — then the rest of the platform consolidation stops Continue reading

BGP ORIGIN attribute manipulation and its impact on the Internet

Border Gateway Protocol (BGP) is the de facto routing protocol of the Internet. It offers built-in mechanisms to allow entities, represented by Autonomous Systems (ASes), to express how they want to send and receive traffic on the Internet. One such mechanism is path attributes, which carry essential routing information and metadata for their associated route. The path selection algorithm processes some of these path attributes in a deterministic sequence to calculate the best path for this specific prefix.

Using our unique position on the Internet, we took an investigative look at one of the well-known mandatory attributes in BGP, the ORIGIN attribute. ORIGIN must be present in every BGP prefix announcement and should not be modified by any router after being set by the originating one. What we found through our own experiments was a dramatic ~70% of observed paths in numerous vantage points have a different ORIGIN value compared to what was set by the originating Autonomous System. This ORIGIN attribute manipulation has a significant impact on the way traffic is forwarded on the Internet, as we’ll explore in this post.

BGP ORIGIN and its operational history

The ORIGIN attribute indicates how a route was injected Continue reading

HN835: The Pros and Cons of Shortest Path Bridging (SPB)

Shortest Path Bridging (SPB) remains an intriguing and reliable fabric technology, offering a unique approach to Ethernet that differs from more widely deployed fabrics such as EVPN/VXLAN. Jeff Wilson joins Ethan and Drew to share his experience designing and managing SPB-based fabrics. Together they discuss how SPB simplifies multicast, essential hardware design considerations for scaling,... Read more »

Hedge 313: Out of Band Management Networks

Most designers and operators default to carrying all traffic–including network management traffic–across the same paths as application data, or in band. Is this the right choice, or should operators seriously consider creating an out-of-band network just for network management? If you decide to build an out-of-band network, what are some of the considerations and lessons learned? Daryll Swer joins Tom and Russ to discuss.


download

IPB204: Tayga and IPv6 Translation

Andrew Palardy joins the hosts to discuss how Tayga, the open-source NAT64 daemon for Linux, is being updated to ensure it is up to date with all the current RFCs. Andrew explains how recent RFC compliance and UDP checksum fixes help resolve connectivity issues and how the new eBPF CLAT support arriving in NetworkManager promises... Read more »

Introducing Cache Response Rules

Today we’re excited to announce Cache Response Rules. These are a new rule type that runs after an origin server replies but before Cloudflare caches the content. 

If you've ever been irked watching something that should easily sail out of cache get dragged back to the origin by a stray Set-Cookie or wrong Cache-Control, headers that are sometimes hard or impossible to strip or change on the origin itself, then Cache Response Rules is that fix, applied at exactly the right moment.  

When and how caching decisions are made

A CDN cache and an origin server work as a pair. Their goal is to answer from the cache whenever possible and only go back to the origin when the edge can’t respond. Every point of cache hit ratio comes from getting that division of labor right. Check the cache when we shouldn't, and we waste a lookup that was always going to miss. Check it too rarely, the origin serves traffic the edge should have absorbed and the performance win evaporates.

Importantly, the origin guides the cache. When it returns a cacheable asset, its response headers tell Cloudflare how long it’s OK to serve it, when and Continue reading

What Happens to a VM’s IP When It Moves During Migration?

Why VM IP identity needs handling on Kubernetes

A KubeVirt VM runs inside a pod. That is the trick that lets Kubernetes schedule a VM like any other workload. It also means the VM and the pod have different lifecycles. The VM is long-lived and has a stable identity. The pod is disposable. When the VM reboots, gets evicted, or live-migrates, the pod underneath is destroyed and a new one is created.

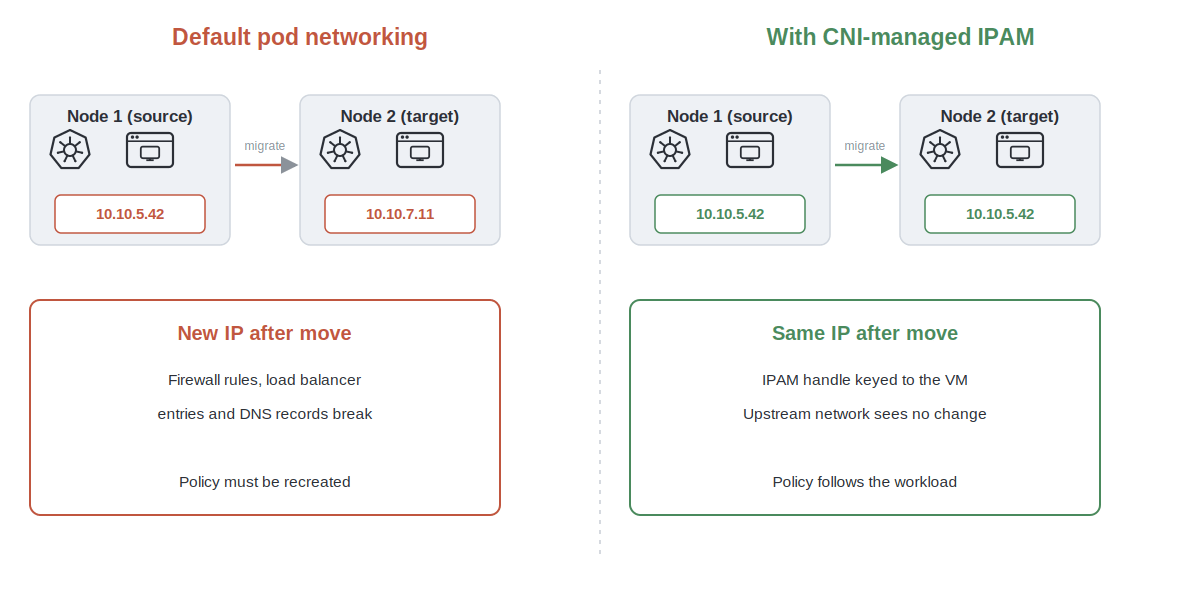
That matters because a VM’s IP is load-bearing. Firewall rules, load balancer entries, and DNS records all point at it. On Kubernetes, standard pod IPAM ties the address to the pod, so a new pod would mean a new IP, and a changed IP is what breaks those dependencies. KubeVirt on its own does not carry the IP across a migration. Its issue tracker has a user reporting exactly this, with a maintainer confirming sticky IPs were never built into the project. The network identity needs something to carry it. That something is Calico.

The diagram below shows the difference this makes. Default pod networking on the left, Calico on the right.

How Calico keeps the IP

Calico’s approach is elegant and specific. Instead of building the IPAM Continue reading

TCG080: Skills Over MCP and More

What if your MCP server shipped with its own manual? Angie Jones, VP of Developer Experience at the Agentic AI Foundation, joins William and Eyvonne to break down the Skills Over MCP working group effort, which delivers Agent Skills through MCP’s existing resources primitive (think voice over IP, not skills versus MCP). Angie shares her... Read more »

NAN127: Scaling Network Automation Communities

Eric Chou welcomes Florian Lohden, a NetDevOps engineer and co-founder of the NetAuto Group, to discuss his community-building efforts and his latest adventures in network automation. Together they explore how adopting software development practices can help with network automation, and the importance of sharing knowledge within networking communities. Florian also talks about how he balances... Read more »